

Extract Text
Reads the text of a PDF page by page, with every word and its position on the page.
The Extract Text action reads the text of a PDF. For every page you get the whole text and the list of words, each with its position, its row on the page and its font. Use the page text for simple searches, or pass the result to Area Mapper to pick values out of fixed places, such as an invoice number or a total.
Add the action
In the Process Designer toolbox, open PDF and pick Extract Text (or type Extract Text in the search box).
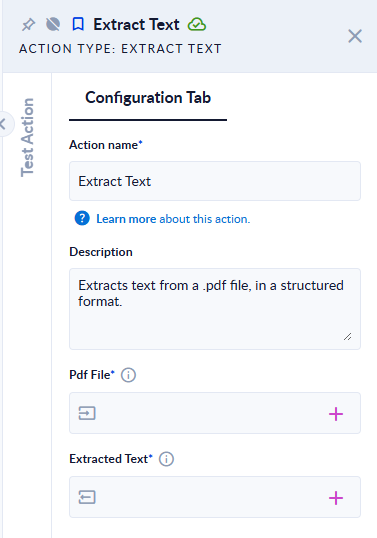
Inputs and outputs
| Field | Direction | Type | Required | What to put / what you get |
|---|---|---|---|---|
| Pdf File | Input | File | Yes | The PDF to read. |
| Extracted Text | Output | List of any type | Yes | One item per page (see below). |
What you get
Each item of Extracted Text describes one page:
| Property | What it holds |
|---|---|
PageNumber | The page number, from 1. |
Text | All the text of the page, as one string. |
Words | Every word of the page, ordered by row then left to right. |
Each word has Id (its number on the page), Text, FontName, TextOrientation and Position:
| Position property | Meaning |
|---|---|
Xleft, Xright | Left and right edge of the word. |
Ytop, Ybottom, Ymid | Top, bottom and middle height of the word. |
Height | Ytop minus Ybottom. |
PageRow | The row of the page the word sits on (1 is the top row). |
PageRowWordOrder | The word's place in its row, from the left. |
Positions are in PDF points (1/72 inch), measured from the bottom-left corner of the page: Y grows upwards, so a word near the top of the page has a large Ytop.
Example
A PDF whose first page has the lines Invoice INV-2026-001, Customer: ACME Ltd and Total 250 EUR gives, for page 1 (first word only):
{
  "PageNumber": 1,
  "Text": "Invoice INV-2026-001Customer: ACME LtdTotal 250 EUR",
  "Words": [
    {
      "Id": 1, "Text": "Invoice", "FontName": "Helvetica", "TextOrientation": "Horizontal",
      "Position": { "Xleft": 50, "Xright": 94.352, "Ytop": 790.052, "Ybottom": 780, "Ymid": 785.026,
                    "Height": 10.052, "PageRow": 1, "PageRowWordOrder": 1 }
    }
  ]
}
Good to know
- In
Text, lines can be joined without a space or line break (…INV-2026-001Customer…). When you need clean lines, rebuild them fromWordsusingPageRow. - Only text stored as text in the PDF is read. A scanned page (an image) gives no words.
- The input must have the
.pdfextension, otherwise the step fails withInput file extension should be '.pdf', found => …. - Large PDFs produce large outputs; extract only what you need later with Area Mapper or Extract Objects.